How to Handle Missing Data in Clinical Research
Introduction
Missing data is one of the most common problems in clinical research, especially in retrospective studies and patient follow-up. It can weaken statistical power, distort results, and reduce trust in an essay or paper if it is not handled correctly. For medical students, doctors, and researchers, the key is not to “fill everything in,” but to understand why data are missing and choose the right method. A clear missing-data strategy improves validity, transparency, and review outcomes.
1. Why Missing Data Matters in Clinical Research
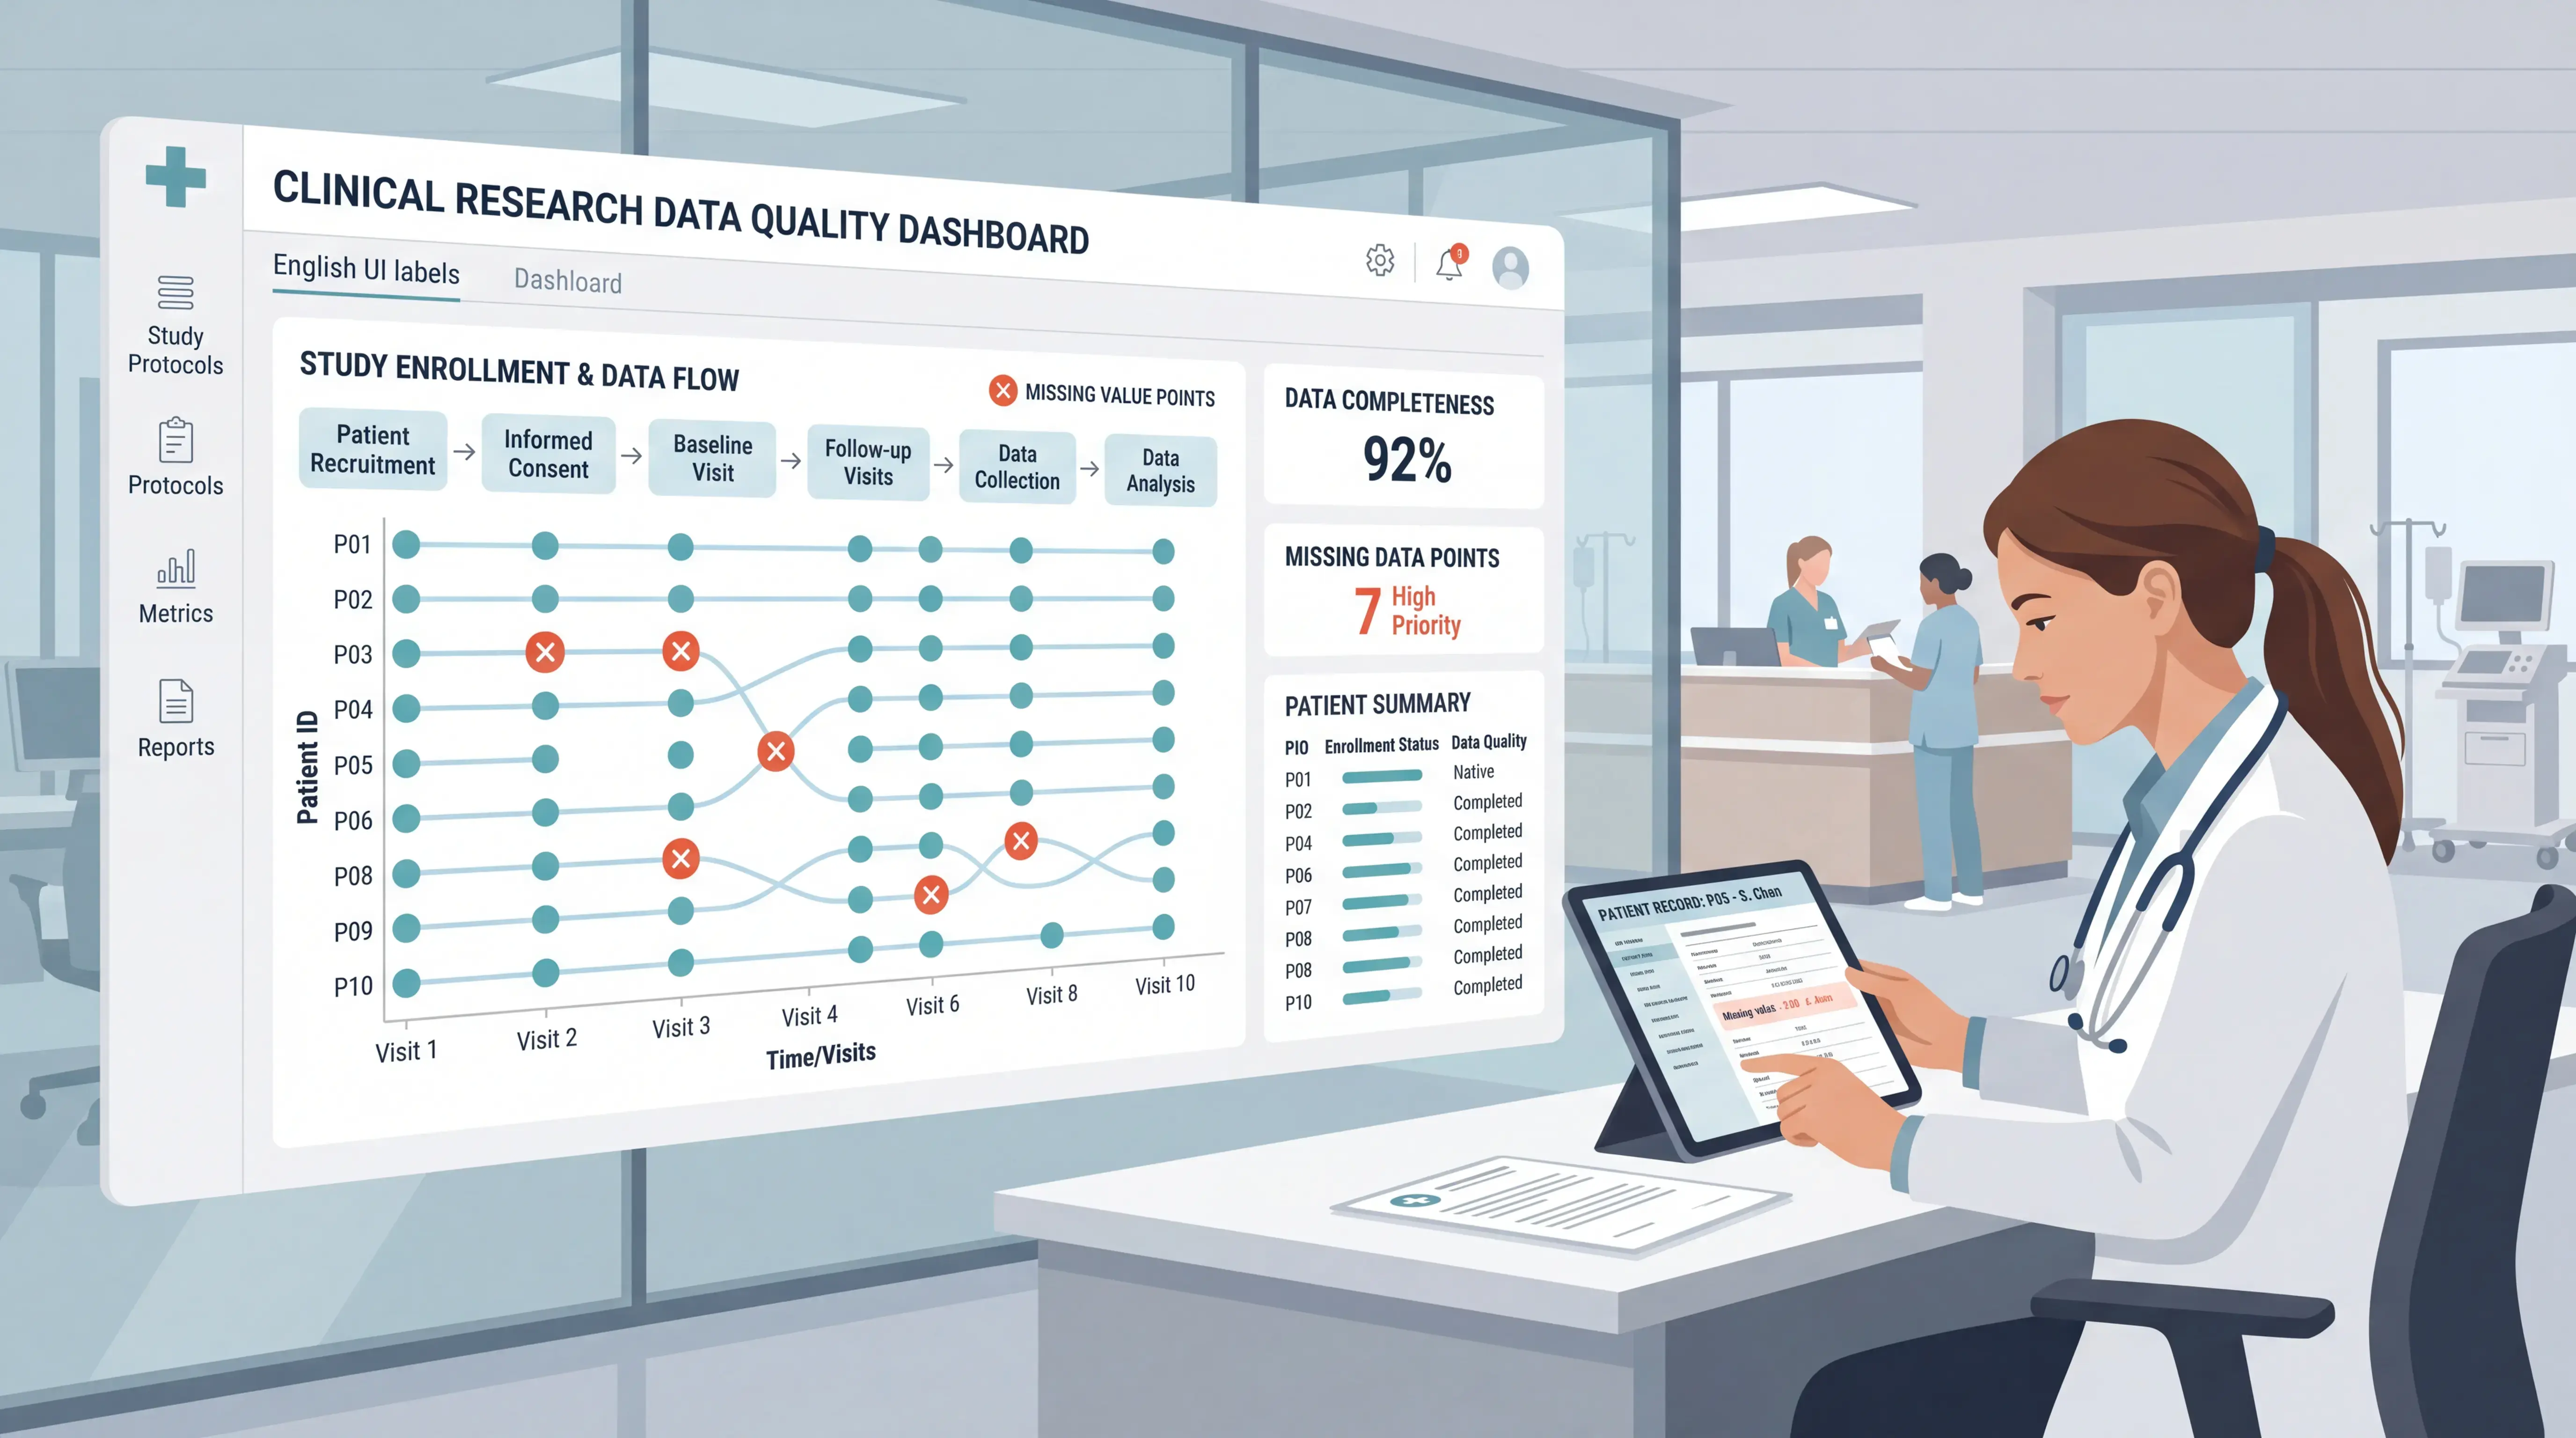
Missing data is not a minor technical issue. It can change the estimated effect of a treatment, bias associations, and make an essay or manuscript less credible. In clinical studies, missingness often comes from dropout, loss to follow-up, missed visits, data entry errors, or incomplete records during long observation periods.
A study with a high missing rate may still be usable, but only if the mechanism is understood. Reviewers often look closely at how the missing data were handled. If you ignore it, the conclusions may look precise but be unreliable. That is why missing data should be described clearly in the Methods and Results sections.
In practice, you should first ask three questions:
- Why is the data missing?
- What type of missingness is it?
- Which variables are affected, and how important are they?
These questions shape every later decision.
2. Identify the Cause Before You Choose a Method
The first step is to confirm whether the data are truly missing. Not every empty field is a missing value. Sometimes the variable simply should not exist for that patient. For example, if a patient never developed the outcome under study, the absence of that outcome is not missing data.
2.1 Common clinical causes
Missing data usually comes from:
- Patient dropout or withdrawal
- Loss to follow-up
- Missed assessments
- Human error during data entry
- Improper storage or delayed updates
- Exclusion of ineligible cases after screening
Each cause has a different statistical implication. A patient who drops out after one visit is very different from a patient whose file was never collected correctly.
2.2 Distinguish missingness from inapplicability
This distinction is essential in clinical research. If a variable cannot logically exist for a patient, it should not be treated as missing. Incorrectly labeling such values as missing can lead to artificial imputation and biased results.
Good data handling starts with accurate classification, not with automatic replacement.
3. Understand the Three Main Missing-Data Mechanisms
Missing data mechanisms matter because they determine which method is appropriate. In standard clinical research, missingness is usually described in three categories.
3.1 Missing Completely at Random, MCAR
MCAR means the probability of missingness is unrelated to any observed or unobserved variable. In theory, deleting these cases does not introduce bias, although it still reduces sample size.
This is the most favorable mechanism, but it is uncommon in real-world studies.
3.2 Missing at Random, MAR
MAR means missingness is related to observed data, but not to the missing value itself. For example, follow-up may be more likely to fail in certain age groups or regions, even if the missing variable is not directly causing the absence.
This mechanism is common in clinical datasets and often supports model-based imputation.
3.3 Missing Not at Random, MNAR
MNAR means missingness is related to the missing value itself or to unobserved factors. For example, sicker patients may be more likely to drop out, and that dropout is linked to the unrecorded outcome.
This is the hardest case. It often cannot be fully solved by simple imputation. Sensitivity analysis becomes important.
You usually cannot test the mechanism directly. You infer it from the clinical process, follow-up pattern, and data collection logic.
4. Describe Missing Data Clearly in the Essay or Manuscript
In any clinical essay or paper, missing data should be reported transparently. Reviewers expect to know how much data are missing, which variables are affected, and what was done next.
A strong report usually includes:
- The number and percentage of missing values
- Which time points or variables were affected
- Whether dropout occurred early or late
- Whether missingness was handled by deletion or imputation
- Whether sensitivity analyses were performed
If possible, use a flow diagram to show patient inclusion, exclusions, dropout, and final analyzable sample. This is especially helpful in retrospective and prospective cohort studies.
Transparency often matters more than a perfect-looking dataset.
5. Main Ways to Handle Missing Data
There are two broad strategies: deletion and imputation.
5.1 Deletion methods
Deletion means removing cases or variables with missing values. Common forms include:
- Listwise deletion, also called case deletion
- Pairwise deletion
- Variable deletion
Listwise deletion is the simplest. It is often used when the amount of missing data is very small. But if missingness is substantial, sample size drops and statistical power declines.
Deletion is more acceptable when:
- Missingness is minimal
- The mechanism is close to MCAR
- The variable is not central to the study question
5.2 Imputation methods
Imputation means replacing missing values with estimated values. It can preserve sample size and reduce data loss, but it must be used carefully.
Common approaches include:
- Mean, median, or mode substitution
- Last observation carried forward, LOCF
- Regression-based imputation
- Multiple imputation
Each method has limits. None of them can perfectly recover the true original data.
6. Common Imputation Methods and Their Limits
6.1 Mean, median, or mode substitution
For continuous variables, missing values may be replaced by the mean or median. For categorical variables, a mode-based approach or a separate category may be used in some settings.
This method is easy, but it reduces variance and can distort standard errors. It is more suitable for small-scale missingness in simple datasets.
6.2 Last observation carried forward
LOCF fills in a missing value using the last recorded value. It is simple and fast, especially in longitudinal studies.
But it assumes the patient’s status remained stable after the last observation. That assumption is often unrealistic in clinical research. For that reason, LOCF is now viewed cautiously.
6.3 Multiple imputation
Multiple imputation creates several plausible versions of the missing values, analyzes them separately, and combines the results. It is widely used because it reflects uncertainty better than single-value replacement.
It is especially useful when:
- Missingness is moderate
- Variables are related to each other
- The dataset is suitable for model-based estimation
Software such as R or SAS is often used to implement it. Even so, the result is still an estimate, not the original truth.
Multiple imputation is often preferred, but it is not a magic fix.
7. How to Choose the Right Method
There is no universal best method. The choice depends on the variable type, missing rate, and mechanism.
A practical approach is:
- Check whether the variable is core or non-core.
- Evaluate the proportion of missingness.
- Identify whether the pattern is likely MCAR, MAR, or MNAR.
- Match the method to the data structure.
Useful rules of thumb:
- Very low missingness may be handled with simple deletion or basic imputation.
- Moderate missingness often supports multiple imputation.
- Very high missingness, especially above 50% to 60%, may make the variable unreliable for analysis.
If the missing rate is extreme, no method can fully restore the original signal.
8. Prevent Missing Data at the Source
The best strategy is prevention. Once data are missing, every fix is an approximation.
To reduce missing data in clinical research:
- Strengthen follow-up procedures
- Standardize data entry
- Train staff on protocol compliance
- Monitor data quality during collection
- Minimize unnecessary patient burden
- Record reasons for dropout in detail
These steps improve completeness before statistical handling is even needed. In many studies, prevention is more valuable than later correction.
9. Practical Reporting Tips for a Strong Clinical Essay
If you are writing an essay or manuscript, keep the reporting concise and precise.
Include:
- Missing-data percentage by variable
- Reason for missingness if known
- Method used to handle missing values
- Whether the main result changed after sensitivity analysis
Do not overstate certainty. Missing-data handling improves analysis, but it does not fully replace lost clinical information.
A rigorous essay should explain both the data problem and the logic of the solution.
10. Where scifocus.ai Can Help
For students and researchers drafting a clinical essay, scifocus.ai can help structure the paper, organize the missing-data section, and improve clarity in reporting. It is especially useful when you need to turn complex methodology into clean academic English.
If you are preparing a manuscript, proposal, or clinical research essay, scifocus.ai can support faster drafting and more consistent presentation. That makes it easier to focus on the real scientific issue, not just the wording.
Conclusion
Missing data is unavoidable in clinical research, but poor handling is not. The right approach starts with identifying the cause, classifying the mechanism, and choosing a method that fits the dataset. Deletion works only in limited cases. Simple substitution is easy but imperfect. Multiple imputation is often more robust, but it still cannot restore the original truth.
For medical students, doctors, and researchers, the goal is clear. Report missing data transparently, handle it cautiously, and prevent it early whenever possible. If you want help drafting a strong clinical research essay with cleaner structure and clearer methodology, consider using scifocus.ai to streamline your writing workflow.
Did you like this article? Explore a few more related posts.
Start Your Research Journey With Scifocus Today
Create your free Scifocus account today and take your research to the next level. Experience the difference firsthand—your journey to academic excellence starts here.